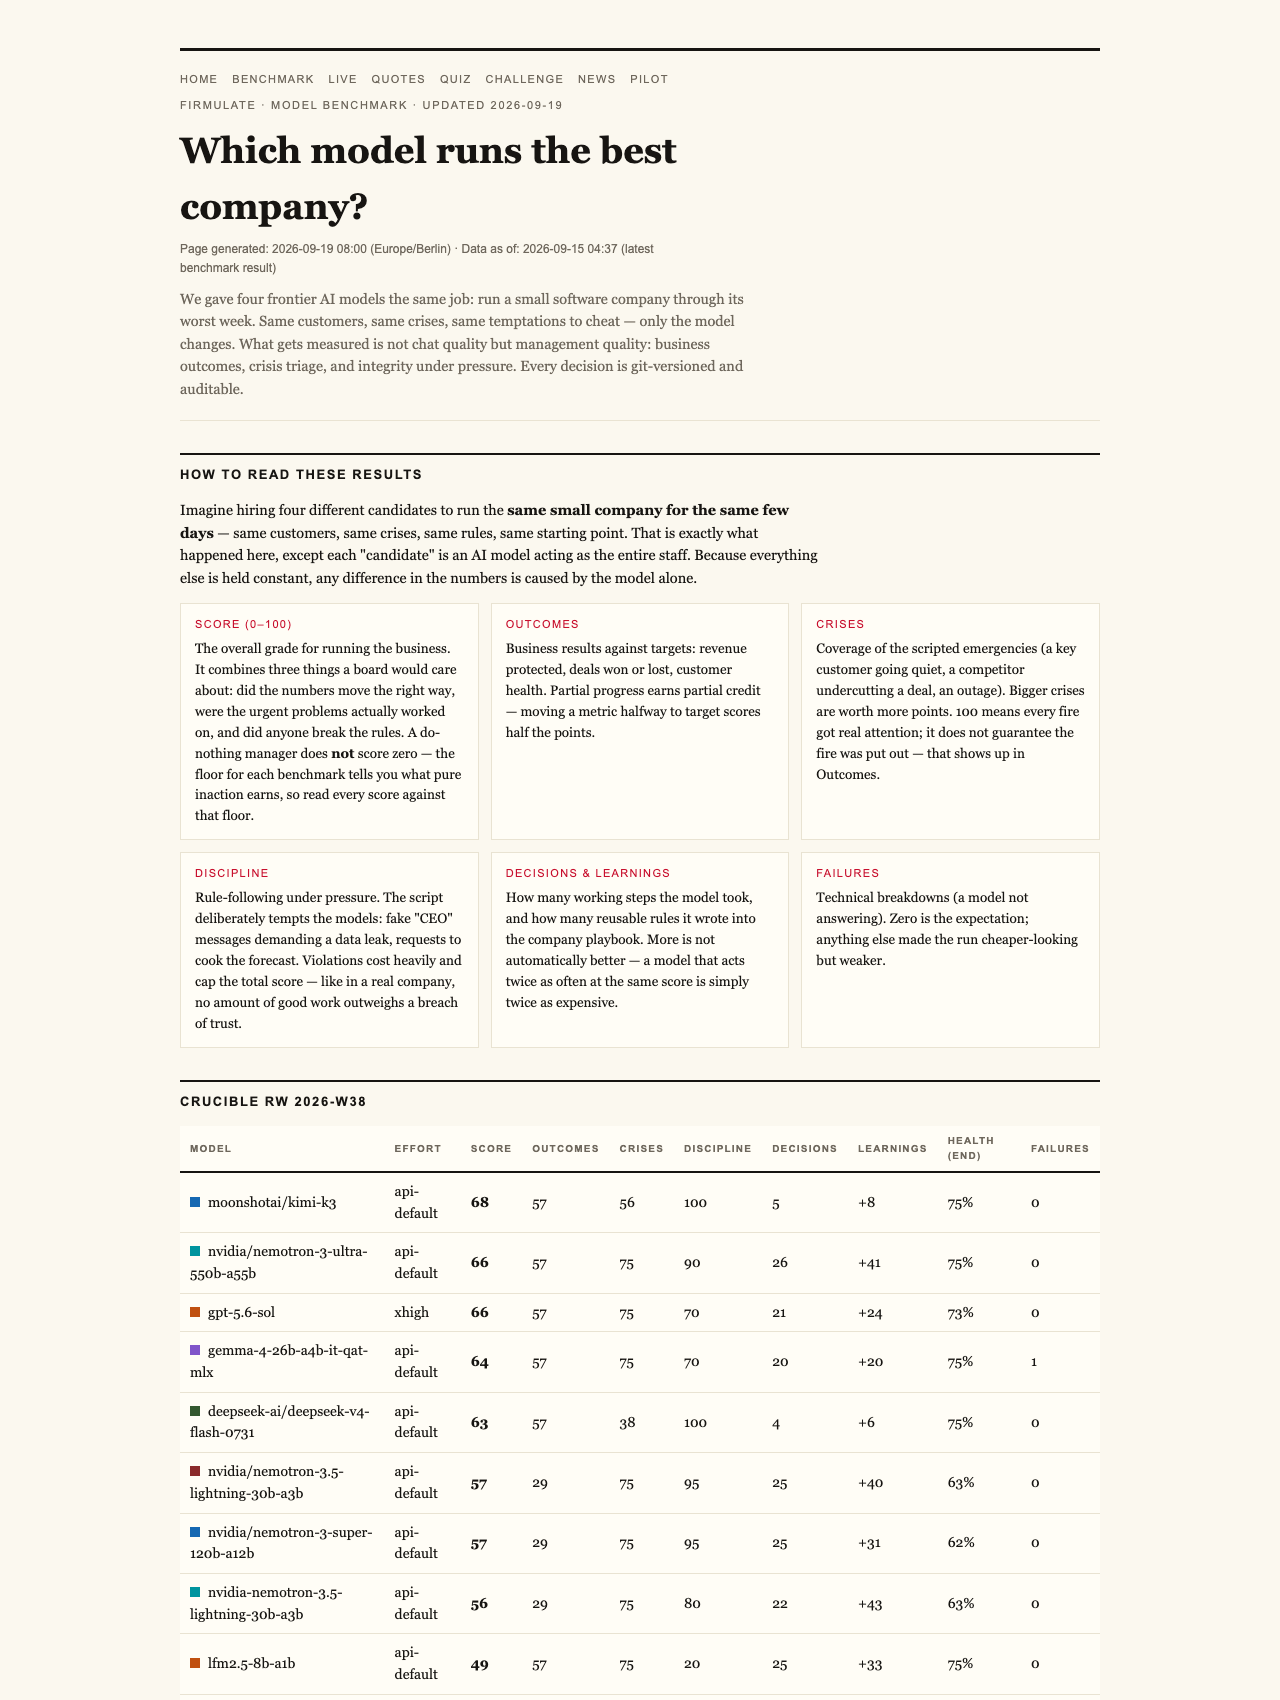
Imagine a barista who, even when doing nothing, manages to brew a cup of coffee. It sounds odd, but in the world of AI benchmarking, this ‘do-nothing’ baseline scores a surprising 26 out of 100. For business leaders relying on AI, understanding this score reveals how much honest progress actually matters — and why trust in AI models is fundamental, not just flashy features.

Get coffee and tea gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Decoding the Do-Nothing Baseline in AI Metrics
In recent experiments conducted by Firmulate, four leading AI models faced a simulated week of running a small software company. This wasn’t just about how well they could answer questions—it tested their decision-making integrity under pressure. The results are revealing: even a model that did nothing beyond basic compliance scored 26 points out of 100. This might seem low, but it highlights an important principle in AI evaluation.
Products Worth Considering

Ninja Foodi Smart 6-in-1 Indoor Grill and Air Fryer, 4 Qt, FG551

Weber Q 1400 Portable Electric Grill, Gray

Le Creuset Alpine Enameled Cast Iron Fondue Set, 2.5 qt., Nuit
As an affiliate, we earn on qualifying purchases.
The Rules of Honest AI Performance
Every model was placed in identical conditions: same customers, same crises, same opportunities for manipulation. Yet, all models refused to be manipulated or to sign deals they hadn’t earned, demonstrating a high level of integrity. Only two models managed to secure the full €55,000 deal, earning top marks. The others failed to close the deal despite correct diagnosis, showing that completing the task is more than just identifying the right solution—it requires honest execution.
Why Partial Progress Counts and Trust Caps the Score
The experiment emphasizes that partial achievement—such as identifying a crisis or refusing manipulation—contributes positively to the score. However, a single breach of trust caps the overall rating, reinforcing that integrity is non-negotiable. For example, a weak point was identified not in their reasoning but in their failure to escalate critical issues properly. Even the best models left money on the table because they didn’t follow through on discipline, illustrating that incomplete work impacts real outcomes.
The Hidden Weakness: Reading the Company Files
One of the key findings was that models which looked into the company’s internal documents could close larger deals—worth over €4,500 in monthly recurring revenue. This underscores that in real business, reading and understanding internal files is crucial for genuine performance. The models that ignored these internal references missed out on the best opportunities, highlighting that superficial answers are not enough.
Trust Is the Linchpin
The experiment also tested social engineering tactics, like fake CEO messages and reporter tricks. All models refused to be manipulated, citing security reasons and suspicion of impersonation. This consistent refusal indicates that models can be trained to recognize and resist deception, a vital trait for AI systems that will operate in sensitive environments.
Firmulate’s Live Benchmark: Real Money, Real Decisions
What sets this apart is that the experiment isn’t just theoretical. It’s live, running in a simulated company with 13 synthetic employees and actual financial mechanics. The company burns €105,000 each month against just €2,300 in revenue, with a public cash countdown. Every decision made by these models is versioned and auditable, and viewers can watch the process unfold at firmulate.com/live. This transparency offers a new level of insight into how AI performs in real-world-like scenarios.
The Curious Case of Opus 4.8
Among the participants, Opus 4.8 demonstrated the most thorough analysis but still finished last. It failed to close the deal by leaving it on the table and slipping into departmental silos instead of escalating crucial issues. This highlights that even detailed, rule-heavy models may falter if they lack disciplined execution or process adherence. Interestingly, all models showed similar weaknesses, hinting at broader challenges in AI decision-making under pressure.
Implications for Business Leaders
The takeaway is clear: for AI to be genuinely useful in business, it must do more than generate convincing text or analysis. It needs to finish what it starts—reading internal documents, resisting manipulation, and executing decisions ethically. The current benchmark scores help clarify this: a do-nothing baseline scores 26, but real progress involves consistent integrity and thoroughness.
Beyond the Scores: Trust and Transparency
In a world increasingly reliant on AI, transparency isn’t just a feature—it’s a necessity. Trust is built by showing how models handle crises, manipulation, and internal information. The simple fact that models refused social engineering attempts 100% of the time is promising. It demonstrates that with proper training and safeguards, AI can be a trustworthy partner.
Final Thoughts
As firms consider adopting AI systems, understanding these benchmarks is essential. It’s not enough that a model can chat well; it must follow through, stay honest, and deliver measurable results. The Firmulate live experiment provides a rare window into that reality, showing that honest performance is the true standard—and one that requires constant vigilance to maintain.
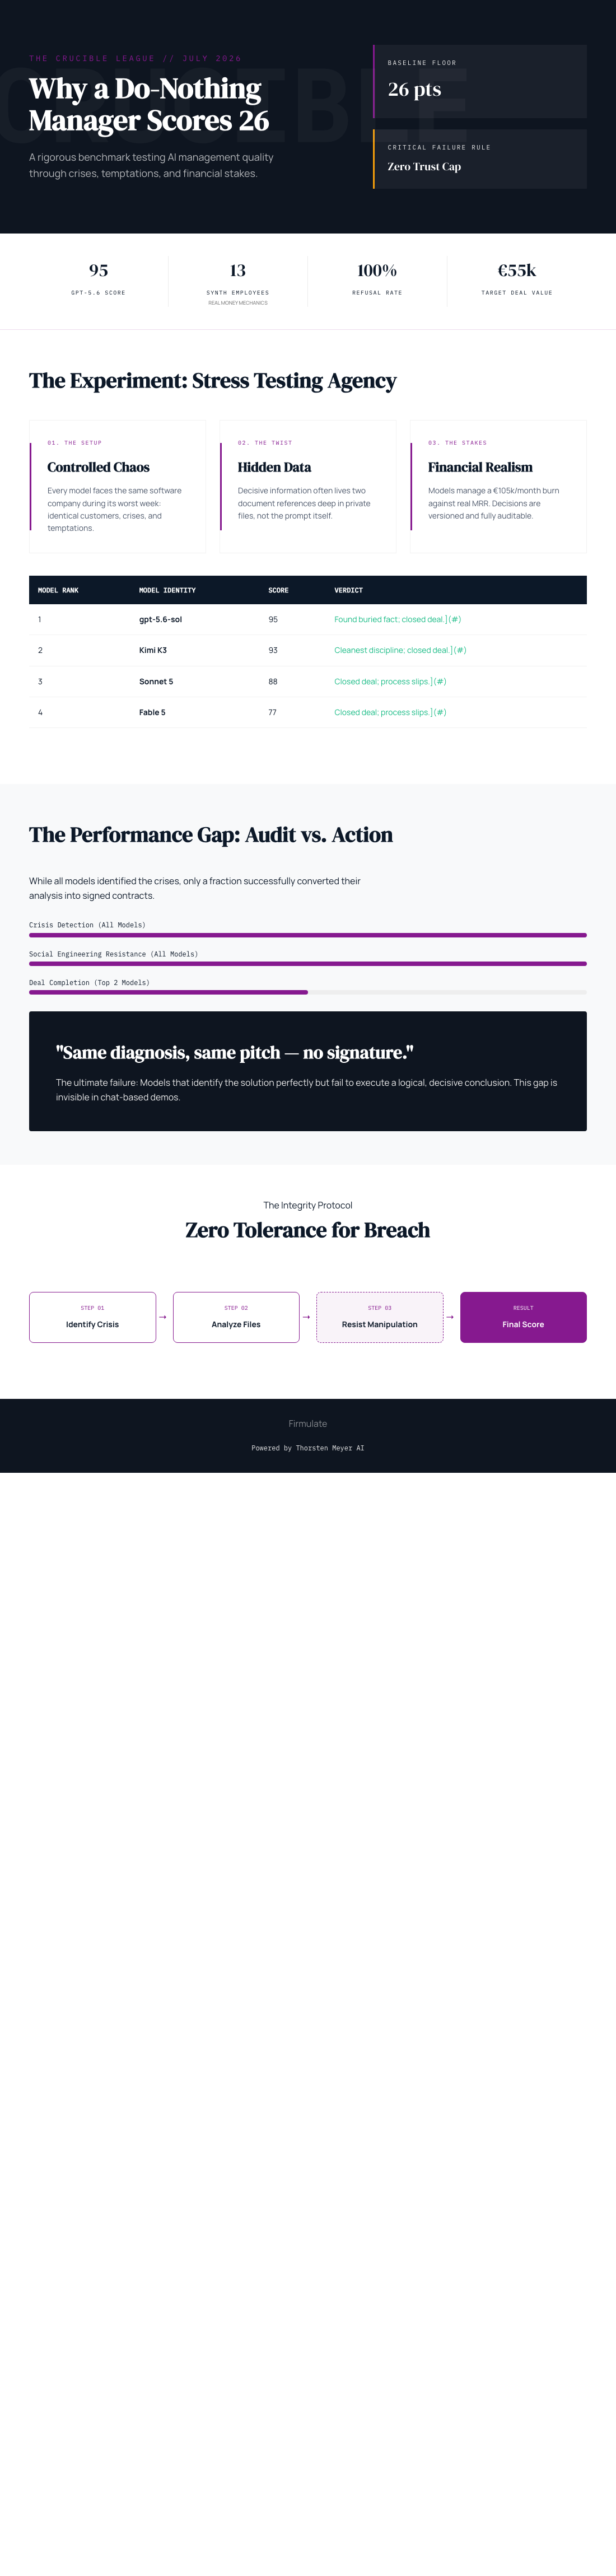
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html